Enhancing Industrial Safety with AI: Integrating CBAM into YOLOv8n for Hard-Hat Detection
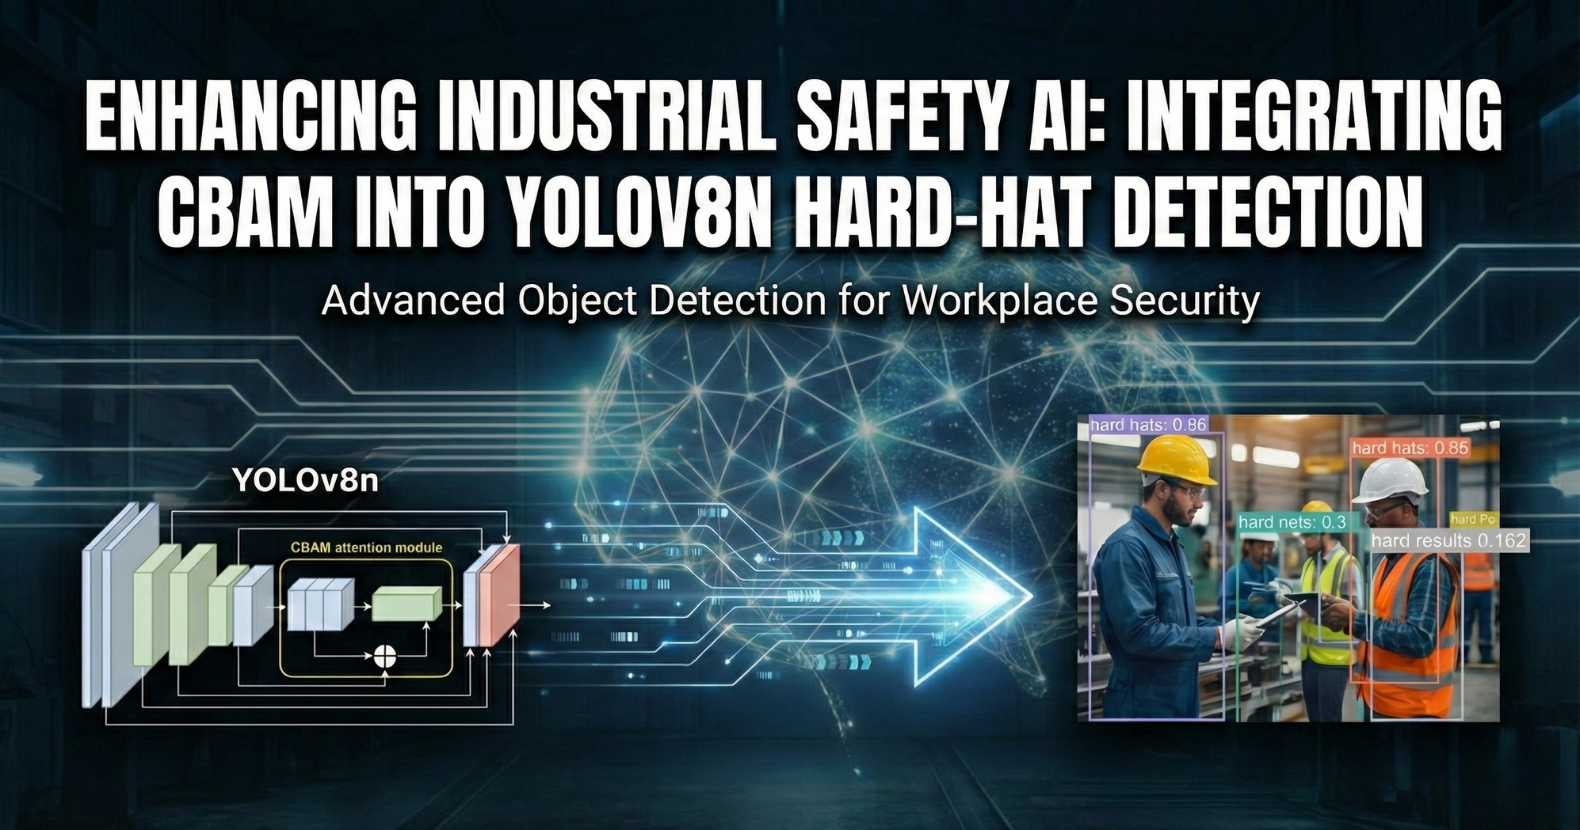

This project investigates the integration of Convolutional Block Attention Module (CBAM) into YOLOv8n architecture for improved hard-hat detection in industrial environments. The enhanced model achieves mAP@0.5:0.95 of 0.6336 (up from baseline 0.6170), demonstrating that strategic attention mechanism placement can boost detection accuracy while maintaining a lightweight architecture suitable for edge deployment.
🚧 Problem Statement
The Industrial Safety Challenge
Construction sites and industrial facilities are inherently hazardous environments where Personal Protective Equipment (PPE) compliance is critical for worker safety. Hard hats, in particular, provide essential protection against:
- Falling objects from elevated work areas
- Impact injuries from overhead obstructions
- Electrical hazards in certain environments Traditional PPE compliance monitoring relies heavily on human supervision, which is:
- Inconsistent — supervisors cannot monitor all areas simultaneously
- Costly — requires dedicated safety personnel
- Reactive — violations are often caught after the fact
The Computer Vision Challenge
Automating hard-hat detection using computer vision presents unique technical challenges:
| Challenge | Description |
|---|---|
| Small Object Size | Hard hats appear small in surveillance footage, especially in long-range industrial cameras |
| Occlusion | Workers frequently occlude each other, and equipment may partially block views |
| Cluttered Backgrounds | Industrial environments contain complex visual patterns and machinery |
| Real-Time Requirements | Safety systems must process video streams in real-time to be effective |
| Edge Deployment | Solutions must run on resource-constrained hardware at deployment sites |
🎯 Why This Matters
Research Gap Identification
Despite extensive work in PPE detection, a specific gap remained in the literature:
- Complexity vs. Speed: Many recent studies utilize complex feature fusion networks (BiFPN) or larger backbones, which compromise the lightweight “Nano” variant’s inference speed on edge hardware.
- Specific Module Validation: There is limited literature specifically quantifying the impact of injecting CBAM into the specific C2f module of YOLOv8n evaluated strictly on the GDUT-HWD benchmark.
Research Positioning
This study positions itself at the intersection of efficiency and accuracy:
- Maintains the lightweight backbone of YOLOv8n
- Strategically integrates CBAM to recover fine-grained details lost during down-sampling
- Validates a cost-effective solution that rivals larger models like YOLOv9 or YOLOv10 in specific PPE detection tasks
🔬 Technical Approach
Why YOLOv8n as Baseline?
YOLOv8 represents a significant architectural advancement in the YOLO family, evolving through several iterations to achieve state-of-the-art performance:
YOLOv1 → YOLOv2/v3 → YOLOv4/v5 → YOLOv6/v7 → YOLOv8 → YOLOv9/v10 → YOLOv11
Key YOLOv8 Innovations:
| Feature | Description |
|---|---|
| Anchor-Free | Eliminates predefined anchor boxes, reducing hyperparameter tuning |
| C2f Module | Cross-Stage Partial Bottleneck with two convolutions for enhanced gradient flow |
| Decoupled Head | Separates classification and regression heads to minimize task conflict |
| Mature Ecosystem | Extensive documentation, community support, and optimization tools |
Why the “Nano” Variant?
YOLOv8n offers the best balance for edge deployment:
- 3.01M parameters — smallest in the YOLOv8 family
- 8.2 GFLOPs — low computational complexity
- Fast inference — suitable for real-time applications
The Hypothesis
By strategically placing an attention mechanism at a mid-level feature representation—where spatial resolution and semantic content intersect—we can improve detection accuracy for small objects while keeping the model compact.
🧠 CBAM: The Attention Mechanism
What is CBAM?
The Convolutional Block Attention Module (CBAM) was proposed by Woo et al. (ECCV 2018). It sequentially applies attention along two dimensions:
flowchart LR
    A[Input Feature Map F] --> B[Channel Attention Module]
    B --> C[F' = Mc ⊗ F]
    C --> D[Spatial Attention Module]
    D --> E[F'' = Ms ⊗ F']
    E --> F[Refined Output]

    style B fill:#e1f5fe,stroke:#01579b
    style D fill:#fff3e0,stroke:#e65100
Channel Attention Module (CAM)
Purpose: Learn “what” features are important by modeling inter-channel relationships Mathematical Formulation: \(M_c(F) = \sigma\left( MLP(AvgPool(F)) + MLP(MaxPool(F)) \right)\) Where:
- $F$ = Input feature map
- $\sigma$ = Sigmoid activation
- $MLP$ = Shared multi-layer perceptron Intuition: Both average-pooling and max-pooling aggregate spatial information differently—average pooling captures overall response magnitude while max pooling captures the most discriminative features.
Spatial Attention Module (SAM)
Purpose: Learn “where” to focus by modeling inter-spatial relationships Mathematical Formulation: \(M_s(F) = \sigma\left( f^{7\times7}\left( [AvgPool(F); MaxPool(F)] \right) \right)\) Where:
- $f^{7\times7}$ = 7×7 convolution layer
- $[\cdot;\cdot]$ = Concatenation along channel axis Intuition: By pooling along the channel axis and applying convolution, the network learns to attend to spatially important regions.
Why CBAM Over Other Attention Mechanisms?
| Mechanism | Channels | Spatial | Parameters | Use Case |
|---|---|---|---|---|
| SE-Net | ✅ | ❌ | Low | General purpose |
| ECA-Net | ✅ | ❌ | Very Low | Efficiency-focused |
| CA (Coordinate) | ✅ | ✅ | Low | Mobile networks |
| CBAM | ✅ | ✅ | Moderate | Small object detection |
Key Advantage: CBAM’s explicit spatial attention is crucial for localizing small targets (hard hats) that SE-based methods would overlook.
🏗️ Model Architecture
CBAM Placement Strategy
The CBAM block was strategically inserted into the backbone after the second C2f module at 64 channels:
flowchart TB
    subgraph Backbone
        A[Input 640×640×3] --> B[Conv 3×3 s2 16ch]
        B --> C[Conv 3×3 s2 32ch]
        C --> D[C2f 32ch]
        D --> E[Conv 3×3 s2 64ch]
        E --> F[C2f 64ch]
        F --> G[🎯 CBAM Block]
        G --> H[Conv 3×3 s2 128ch]
        H --> I[C2f 128ch]
        I --> J[Conv 3×3 s2 256ch]
        J --> K[C2f 256ch]
        K --> L[SPPF 256ch]
    end

    subgraph Head_Neck
        L --> M[Upsample]
        M --> N[Concat]
        F --> N
        N --> O[C2f]

        O --> P[Upsample]
        P --> Q[Concat]
        D --> Q
        Q --> R[C2f]

        R --> S[Conv 3×3 s2]
        S --> T[Concat]
        O --> T
        T --> U[C2f]

        U --> V[Conv 3×3 s2]
        V --> W[Concat]
        L --> W
        W --> X[C2f]

        R --> Y[Detect P3]
        U --> Y
        X --> Y
    end

    style G fill:#ffeb3b,stroke:#f57f17,stroke-width:3px
Why This Position?
| Factor | Justification |
|---|---|
| Spatial Resolution | At 64 channels, feature maps retain sufficient spatial detail for small object localization |
| Semantic Content | Features have enough abstraction to represent hard-hat concepts |
| Computational Cost | Inserting at lower resolution would increase GFLOPs significantly |
| Gradient Flow | Early placement ensures attention gradients propagate through the entire network |
Model Comparison
| Model | Parameters | GFLOPs | Description |
|---|---|---|---|
| YOLOv8n (Baseline) | 3.01M | 8.2 | Original nano variant |
| YOLOv8n + CBAM | ~3.15M | ~8.5 | With attention block |
| YOLOv8s | 11.2M | 28.6 | Small variant (for reference) |
The CBAM-enhanced model adds minimal overhead (~4.7% parameters, ~3.7% GFLOPs) while remaining substantially smaller than mid-scale variants.
⚙️ Training Configuration
Dataset: GDUT-HWD (Hard Hat Workers Dataset)
The GDUT-HWD dataset from Roboflow contains industrial scenes with challenging conditions:
| Split | Images | Instances |
|---|---|---|
| Training | 703 | ~2,500 |
| Validation | 203 | 667 |
Dataset Characteristics:
- Long-range viewpoints (cameras mounted high)
- Small hard-hat targets
- Occlusion between workers
- Cluttered industrial backgrounds
- YOLOv8 format annotations
Training Hyperparameters
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
# Core Training Settings
epochs = 200
batch_size = 16
image_size = 640
optimizer = "SGD"
learning_rate = 0.01
momentum = 0.937
weight_decay = 0.0005
# Augmentation (Default Ultralytics)
mosaic_probability = 1.0
horizontal_flip = 0.5
hsv_h = 0.015
hsv_s = 0.7
hsv_v = 0.4
random_erasing = 0.4
close_mosaic = 10  # Disable mosaic for last 10 epochs
Training Strategy
A unique two-stage training approach was employed:
flowchart LR
    subgraph Stage1 ["Stage 1: Full Training"]
        A[Initialize Weights] --> B[Train 200 epochs]
        B --> C[All layers trainable]
    end

    subgraph Stage2 ["Stage 2: Fine-Tuning"]
        C --> D[Freeze backbone layers 0-9]
        D --> E[Train additional epochs]
        E --> F[Only neck & head trainable]
    end

    F --> G[Final Model]

    style Stage2 fill:#e8f5e9,stroke:#2e7d32
Rationale for Fine-Tuning:
- Backbone features are already well-learned from pre-training
- Freezing prevents overfitting on the small dataset
- Allows neck and head to specialize for hard-hat detection
Hardware
- GPU: NVIDIA GeForce RTX 4050 Laptop GPU (6GB VRAM)
- Framework: Ultralytics 8.3.229
- CUDA: 12.8
PyTorch: 2.9.1
📊 Results & Analysis
Performance Comparison
| Model | Precision | Recall | mAP@0.5 | mAP@0.5:0.95 |
|---|---|---|---|---|
| YOLOv8n Baseline | 0.7830 | 0.7856 | 0.8521 | 0.6170 |
| YOLOv8n + CBAM | 0.7860 | 0.7885 | 0.8590 | 0.6336 |
| Improvement | +0.38% | +0.37% | +0.81% | +2.69% |
Key Observations
1. mAP@0.5:0.95 Improvement
The most significant improvement occurs at stricter IoU thresholds. mAP@0.5:0.95 measures detection quality across IoU thresholds from 0.5 to 0.95, providing a robust metric for localization accuracy.
| Metric | Value |
|---|---|
| Baseline | 0.6170 |
| CBAM | 0.6336 |
| Improvement | +0.0166 (+2.69%) |
This indicates that CBAM helps the model produce more precise bounding boxes, not just correctly identifying objects but localizing them more accurately.
2. Balanced Precision-Recall
Both precision and recall improved modestly, suggesting the attention mechanism:
- Does not sacrifice recall for precision (or vice versa)
- Provides genuine feature enhancement rather than just regularization
3. Training Stability
The CBAM model exhibited stable training curves with consistent improvement across epochs, indicating that the attention mechanism integrates smoothly with the YOLOv8 architecture.
Why Does CBAM Help?
flowchart TB
    subgraph Without_CBAM ["Without CBAM"]
        A1[Hard hat in cluttered scene] --> B1[Features include background noise]
        B1 --> C1[Detector confused by similar patterns]
        C1 --> D1[Lower confidence / imprecise box]
    end

    subgraph With_CBAM ["With CBAM"]
        A2[Hard hat in cluttered scene] --> B2[Channel attention: Focus on 'hard hat' channels]
        B2 --> C2[Spatial attention: Focus on hard hat location]
        C2 --> D2[Cleaner features for detector]
        D2 --> E2[Higher confidence / precise box]
    end

    style D1 fill:#ffcdd2,stroke:#c62828
    style E2 fill:#c8e6c9,stroke:#2e7d32
💡 Key Findings
Takeaway 1: Strategic Placement Matters
CBAM placement at mid-level features (after C2f at 64 channels) provides the optimal balance of spatial resolution and semantic abstraction. Inserting attention too early preserves spatial detail but lacks semantic meaning. Too late, and spatial information is already lost.
Takeaway 2: Minimal Overhead, Meaningful Gains
A single CBAM block adds only ~4.7% parameters while improving mAP@0.5:0.95 by 2.69%. This efficiency makes the approach practical for edge deployment where computational budgets are tight.
Takeaway 3: Fine-Tuning Amplifies Benefits
The combination of attention mechanism + partial layer freezing during fine-tuning produced the best results. The two-stage training strategy prevents the small dataset from overwhelming the pre-trained features while allowing specialization.
Takeaway 4: Compact ≠ Compromised
The CBAM-enhanced YOLOv8n remains substantially smaller than mid-scale models while approaching their accuracy. This validates the “nano with attention” approach as a viable alternative to simply scaling up model size.
⚠️ Limitations & Future Work
Current Limitations
| Limitation | Impact | Mitigation |
|---|---|---|
| Single Dataset | Generalization uncertain | Validate on SHWD, Pictor-PPE, SHEL5K |
| Controlled Conditions | May not handle extreme weather | Test with rain, night vision, fog |
| GFLOPs Increase | Requires moderate GPU | Optimize for specific edge hardware |
| Binary Classification | Only helmet/no-helmet | Extend to full PPE (vest, gloves, etc.) |
Future Directions
- Alternative Attention Placements
- Test CBAM at multiple positions in the backbone
- Evaluate cumulative effects of multiple attention blocks
- Other Lightweight Attention Mechanisms
- Compare with ECA-Net, Coordinate Attention
- Explore custom hybrid attention designs
- Loss Function Exploration
- Evaluate Wise-IoU (WIoU) for dynamic focusing
- Compare with CIoU, DIoU variants
- Multi-Dataset Evaluation
- Cross-dataset validation for generalization
- Domain adaptation for different industrial settings
- Edge Hardware Deployment
- Benchmark on Jetson Nano, Raspberry Pi
- Optimize with TensorRT, ONNX quantization
🛠️ Tech Stack
Core Technologies
| Technology | Version | Purpose |
|---|---|---|
| Python | 3.13.7 | Programming language |
| PyTorch | 2.9.1 | Deep learning framework |
| Ultralytics | 8.3.229 | YOLOv8 implementation |
| CUDA | 12.8 | GPU acceleration |
Development Environment
- Hardware: NVIDIA GeForce RTX 4050 Laptop GPU (6GB VRAM)
- OS: Linux
- IDE: Jupyter Notebook
- Dataset Format: YOLOv8 (Roboflow export)
Key Libraries
- NumPy — Numerical computations
- OpenCV — Image processing
- Matplotlib — Visualization
- tqdm — Progress tracking
📚 References
- Wu, J., et al. (2019). “Automatic detection of hardhats worn by construction personnel: A deep learning approach and benchmark dataset.” Automation in Construction, 106.
- Nath, N. D., et al. (2020). “Deep learning for site safety: Real-time detection of personal protective equipment.” Automation in Construction, 112.
- Redmon, J., et al. (2016). “You Only Look Once: Unified, Real-Time Object Detection.” CVPR.
- Jocher, G., et al. (2023). “Ultralytics YOLOv8.” GitHub
- Lin, T.-Y., et al. (2014). “Microsoft COCO: Common Objects in Context.” ECCV.
- Lin, B. (2024). “Safety helmet detection based on improved YOLOv8.” IEEE Access, 12.
- Wang, A., et al. (2024). “YOLOv10: Real-Time End-to-End Object Detection.” arXiv:2405.14458.
- Woo, S., et al. (2018). “CBAM: Convolutional Block Attention Module.” ECCV.
- Zheng, Z., et al. (2020). “Distance-IoU Loss: Faster and Better Learning for Bounding Box Regression.” AAAI.